

 Databases
Primary storage for transactional workloads
Provision by IOPS as well as capacity so MySQL, PostgreSQL and SQL Server get consistent low-latency disk under write-heavy loads.
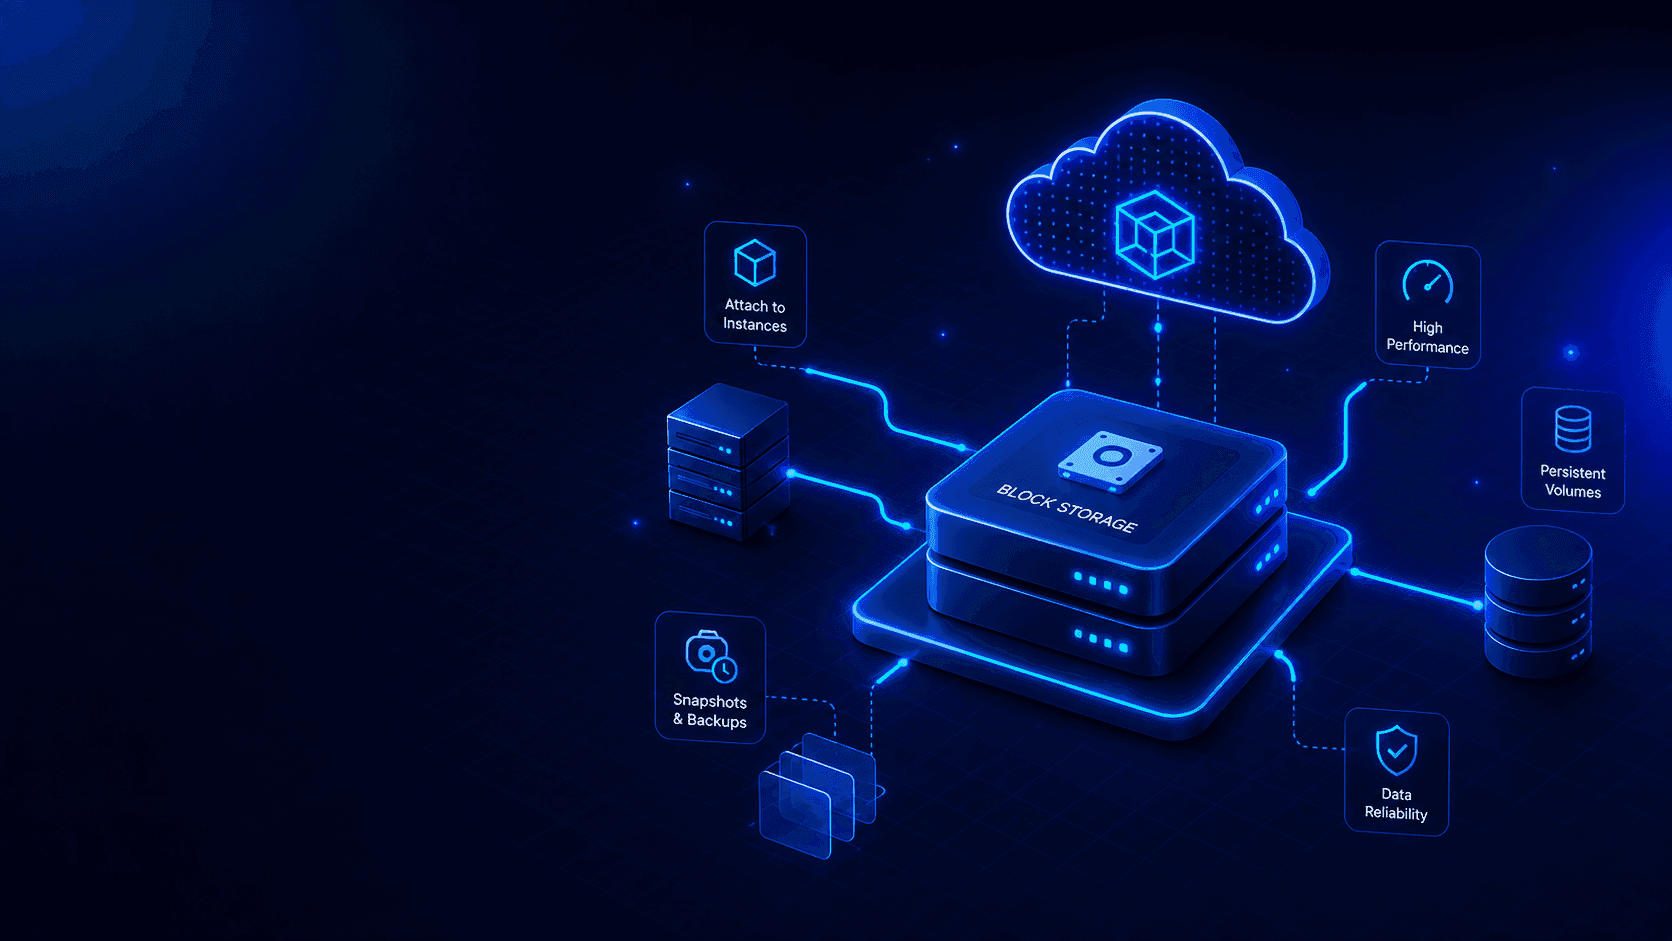
Attach, resize and snapshot persistent volumes without stopping the instance. Triple-replicated inside the UAE region, encrypted at rest, and priced per gigabyte with no minimum commitment.
One volume type, provisioned by the gigabyte, covers everything from a single database to a fleet of Kubernetes persistent volumes.
DatabasesProvision by IOPS as well as capacity so MySQL, PostgreSQL and SQL Server get consistent low-latency disk under write-heavy loads.
 Kubernetes
Mount block volumes as PersistentVolumeClaims through the CSI driver, so StatefulSets keep their data across pod rescheduling.
 Backup target
Schedule daily or weekly snapshots with configurable retention and restore into a fresh volume in minutes, without touching the source.
 ERP & line-of-business
Dedicated-core instances plus triple-replicated volumes give finance and inventory systems the consistency auditors expect.
 Media processing
Attach a large NVMe volume for the duration of a transcoding or rendering job, then detach and delete it once the output is uploaded.
 VDI & dev boxes
Grow a developer's volume live when a project outgrows its allocation, without a reboot or a support ticket queue.
Object storage is the cheapest durable place to put data that is written once and read many times.
NVMe throughout, with no burst-credit model that quietly throttles you three hours into a batch job.
Writes land on three nodes inside the region before acknowledgement. Disk and node failures are invisible to the guest.
Snapshot before every deployment. Restores create a new volume, so the original stays untouched while you verify.
AES-256 on volumes and snapshots, with platform-managed keys and no configuration required from you.
IOPS, throughput and queue depth per volume, so you can tell a slow query from slow storage.
Create, attach, resize and snapshot through the API or Terraform as part of your deployment pipeline.

AES-256
encryption at rest, on by default
Replication happens on every write, before it is acknowledged back to your instance. Snapshots and scheduled backups sit on top of that as a second, independent layer of protection.
3×
replicated writes inside the region
< 1 ms
typical write acknowledgement latency
16 TB
maximum size per single volume
0
downtime required to resize live
Yes. Volumes expand live — the block device grows immediately and you extend the filesystem inside the guest without rebooting. Volumes cannot be shrunk; if you need less capacity, create a smaller volume and migrate the data.
Every block is written to three separate storage nodes inside the region before the write is acknowledged. A single node or disk failure is transparent to the instance. Replication is not a substitute for backup, so we also recommend scheduled snapshots.
NVMe-backed volumes deliver consistent low-millisecond latency with IOPS scaling by volume size. For database workloads we recommend provisioning by IOPS requirement rather than capacity, and we will size it with you.
No — a block volume attaches to one instance at a time, which is how block storage works everywhere. For shared access across many instances, use object storage or a network filesystem, and we can advise which fits.